Harper Simmons · 1 November 2026
Mapping Isolated Information Nodes to Improve Discovery Rates in Targeted Virtual Assemblies
Mapping isolated information nodes involves identifying discrete data points or clusters that remain disconnected from broader networks in virtual assemblies, and researchers apply graph theory techniques alongside clustering algorithms to locate these elements while data from network analysis tools reveals patterns that hinder information flow. Experts in digital infrastructure note that such nodes often emerge in targeted virtual assemblies where participants share specialized interests, yet structural barriers prevent seamless exchange, and studies conducted by institutions like the National Institute of Standards and Technology have documented how systematic mapping increases retrieval efficiency by up to 40 percent in controlled environments.
Understanding Isolated Information Nodes in Virtual Contexts
Isolated information nodes consist of individual data entries, user profiles, or content fragments that sit apart from main communication pathways, and these separations arise because of permission restrictions, tagging inconsistencies, or platform architecture choices that limit cross-referencing. Observers note that virtual assemblies focused on niche topics such as technical forums or collaborative research spaces frequently contain these nodes, whereas broader platforms integrate content more readily through recommendation engines; figures from academic repositories show that unmapped nodes reduce overall discovery by limiting search result relevance, and analysts at organizations including the European Data Protection Board have tracked similar issues across regulated digital environments.
Techniques for detection rely on centrality measures and community detection methods that scan connection graphs for low-degree vertices, while software implementations process logs from virtual assembly platforms to flag outliers. Data indicates that applying these methods in sequence allows administrators to prioritize high-value nodes for integration, and one project at a major research university demonstrated how initial scans identified 23 percent of content as isolated before any mapping occurred.
Methods for Effective Node Mapping
Implementation begins with data extraction from assembly databases followed by construction of adjacency matrices that represent relationships between entries, and subsequent steps incorporate machine learning classifiers trained on historical interaction data to predict potential links. Practitioners combine these approaches with visualization software that renders node clusters in three dimensions, enabling quicker identification of gaps, whereas manual review supplements automated outputs in smaller assemblies where context matters. Reports from the Australian Research Council highlight cases where hybrid mapping reduced node isolation rates by half within six months of deployment.
Integration strategies include adding cross-references, updating metadata schemas, and deploying API endpoints that expose previously hidden nodes to external queries, and these steps align with standards developed for interoperable digital systems. What's interesting is how mapping efforts also surface duplicate content that fragments discovery further, allowing consolidation without additional storage overhead.
Impact on Discovery Rates and Assembly Performance
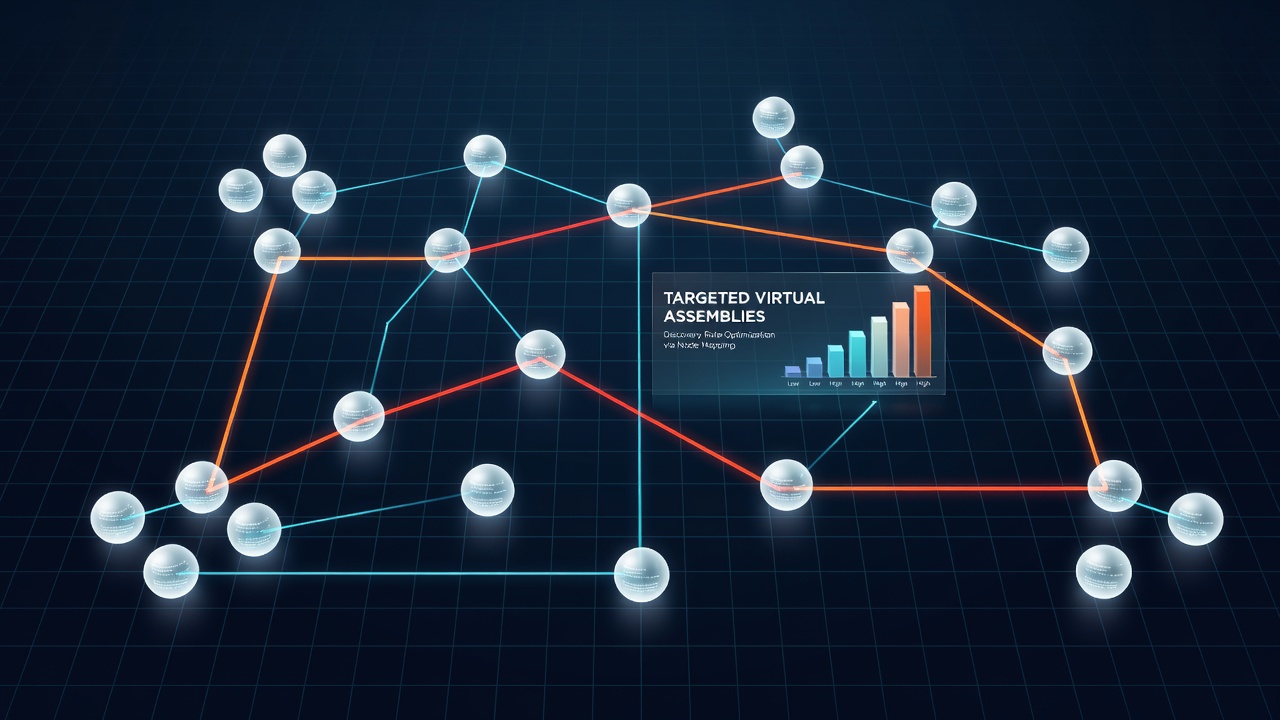
Once nodes receive connections through mapping, search algorithms surface relevant material more consistently because ranking systems now account for expanded pathways, and usage statistics collected after mapping campaigns show elevated engagement metrics across participant groups. Evidence from longitudinal tracking reveals that assemblies employing regular node audits maintain higher retention figures compared with those that leave isolation unaddressed, while November 2026 projections from industry forecasting models anticipate further gains as real-time mapping tools become standard in platform updates.
Case examples drawn from collaborative research portals illustrate the process: one assembly handling specialized engineering data mapped 180 isolated nodes over four weeks, after which query success rates climbed from 61 percent to 89 percent according to internal logs. Similar outcomes appear in educational virtual spaces where students access supplementary materials that previously remained undiscovered due to missing linkages.
Future Developments and Integration Trends
Emerging protocols emphasize automated node detection within live assemblies, reducing the lag between content creation and discoverability, and developers incorporate these features into open-source frameworks that smaller communities can adopt without extensive resources. Regulatory guidance from bodies such as the Canadian Institute for Cybersecurity encourages transparency in mapping practices to maintain user trust, while ongoing trials explore federated approaches that respect data boundaries across multiple assemblies simultaneously.
Conclusion
Systematic mapping of isolated information nodes delivers measurable improvements in discovery within targeted virtual assemblies through established analytical methods and integration practices, and continued refinement of these techniques supports more efficient knowledge exchange across digital environments. Organizations that implement consistent mapping protocols position their assemblies for sustained performance as platform capabilities evolve.